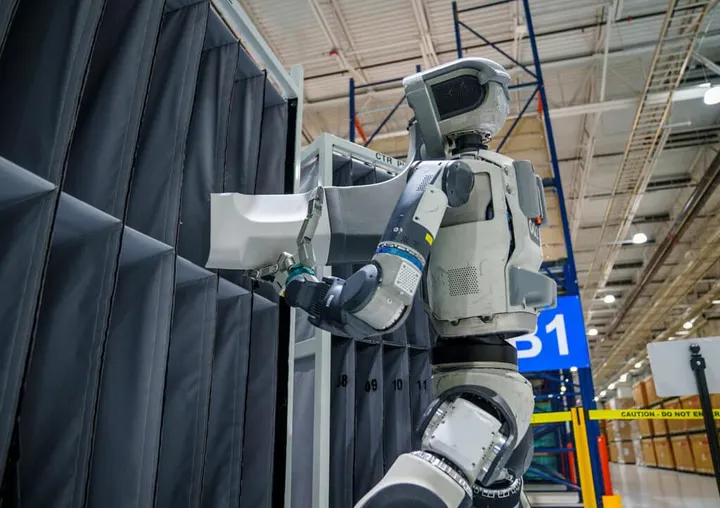
Consider an assembly station where a supplier changes the shape of a connector. A person can watch a colleague fit the new part, try it, and ask when the fit feels wrong. For a robot, that small change exposes several different problems: understanding the instruction, controlling contact, recognizing failure and deciding whether to continue.
Robotics is making a striking advance on the first of those problems. The remaining ones will determine how much work actually changes hands.
On September 10, Skild AI said it had passed a $100 million recurring revenue run rate and 60 paying customers, ten months after its first commercial deployment. It reported work on Blackwell hardware assembly with NVIDIA and Foxconn, a planned S1 deployment in wire harness manufacturing, and kitchen pilots with Mitsui. Those are the company's figures and descriptions, rather than independently verified operating results. A revenue run rate also differs from revenue already earned. Skild's deployment report
The announcement makes a useful moment to examine the emerging promise: machines that can take a demonstration as an instruction. The strongest evidence supports a significant change in how robots acquire tasks. It leaves a separate, harder question about dependable output.
A demonstration becomes an instruction
Skild's S1 technical release dates to August 2026. In its September 10 account of the collaboration, NVIDIA describes an operator supplying one video of a desired task. The model uses it to guide the robot without a new task-specific training run. Demonstrated tasks include repotting a plant and assembling a kit; some sequences last up to ten minutes. NVIDIA's technical account
This approach is called in-context learning. The example is available to the system while it works, rather than being turned into a separate retrained model for that job. A useful analogy is handing an experienced technician a demonstration of a new procedure. The demonstration supplies the local instructions; the ability to interpret them depends on experience acquired beforehand.
That distinction matters. One video is the additional instruction, not the sum total of what went into the machine.
If this becomes reliable, the practical benefit could be substantial for work that changes often. A business could reuse a robot across product variants or shorter runs without repeating as much specialist teaching. That is an economic possibility suggested by the approach, not a measured saving established by the announcement.
Read the denominator
S1's most arresting comparison needs its methodological detail attached. In an internal study using 100,000 hours of pretraining data, Skild reports 66% on unseen tasks for its demonstration-conditioned model, against 9% for the language-conditioned comparison. The authors describe the measure as an average of cumulative per-step success across tasks. They also say people intervened to recover failed rollouts so subsequent steps could be scored, mainly for the baseline. S1's evaluation method
That result does not establish that 66% of complete unfamiliar jobs were finished without assistance. It measures a different thing. Skild also reports that a task-specific comparison eventually reached 86% with 2,000 demonstrations. The experiment supports faster initial adaptation; it does not show that prompting has made further training unnecessary for every performance target.
The distinction is consequential for anyone watching robot videos. A sequence of successful movements, a task completed once, and a shift delivered at the required quality are three different units of evidence. Reporting one clearly makes the others easier to investigate.
It would also be wrong to turn that 66% into an estimated full-job completion rate by multiplying it across steps. The reported metric and intervention procedure do not support that calculation.
The pattern extends beyond Skild
Generalist's August 19 GEN-1.5 report describes another route to learning from demonstrations. Across ten simple, short tasks, the company reports 59% average success from a single example without weight updates. Five minutes of demonstrations per task and ten training steps raised the reported average to 83%. The authors explicitly describe prompted skills as more brittle than fine-tuned ones. Generalist's GEN-1.5 report
The numbers should not be arranged into a leaderboard beside S1. The tasks, inputs and scoring differ. What travels across the two reports is a more useful observation: reaching an initial level of competence quickly and refining that competence remain distinct achievements.
A July research paper, RoboTTT, explores longer memory during robot operation. Its one-demonstration circuit-assembly evaluation separately reports a 65% task-completion score and six fully successful runs out of ten. That separation makes the outcome unusually legible. The system uses changing internal memory parameters during operation, so its mechanism should not be collapsed into S1's description of unchanged model weights. RoboTTT's paper and evaluation
For readers, a better comparison starts with questions: What was unseen? How long was the task? What information accompanied the demonstration? What counted as success? When could a person step in?
The difficult moment is contact
Watching an action leaves important information unspoken. A connector may look aligned while sitting slightly proud of its socket. A screw may turn without engaging its thread. The part's resistance can reveal something that a camera view does not.
FACTR 2, a research paper revised in August, addresses this problem from another direction. The authors estimate external joint torque from a robot's own signals and give extra training emphasis to moments around contact. They report improved progress across five manipulation tasks. The approach is specific to the robot hardware and may need retraining between arms. FACTR 2's results and limitations
The implication is that a better way to specify a task does not erase the importance of sensing and control. A video can communicate the desired sequence. The deployed system must still determine whether its own attempt is going correctly, especially when the real object behaves differently from the example.
The unglamorous work behind these capabilities also remains considerable. The earlier DROID project assembled roughly 76,000 demonstrations across 564 scenes with 50 collectors over twelve months, and released its dataset and collection setup. It is a useful historical reminder of the physical effort involved in building broad robot experience. It is not evidence that S1 uses DROID. DROID's original project
Measure the work that survives the mistakes
For a prospective operator, the useful test is a defined job under representative conditions. A sensible evaluation would track:
- Accepted output: how many completed items pass inspection, including the time spent on rejected work.
- Human attention: every intervention, reset and period of remote assistance, measured against operating hours.
- Recovery: whether a failed attempt is detected, whether a retry succeeds, and how the system hands over unresolved cases.
- Changeover: the total time to introduce a variant, including preparation and validation after the demonstration is recorded.
These are proposed evaluation criteria, not published S1 results. Their purpose is to make the cost of the complete workflow visible. A machine that needs occasional assistance could still be valuable. The assistance must be included when deciding how many stations a person can supervise and how much capacity a deployment adds.
There is also a distinction between keeping the process moving and making an acceptable product. Repeating an insertion until something seems to fit is useful only if the system can establish that the part has been fitted correctly. An impressive recovery can otherwise conceal a defect.
The next convincing evidence would be repeated customer-site results over sustained operating periods, with the task, cycle time, quality checks and human involvement described together. Such reporting would let buyers distinguish fast teaching from dependable production without discounting either.
The advance is worth taking seriously. A demonstration could become a far more accessible interface for directing machines, opening useful automation to work whose instructions change too often to justify a bespoke project each time.
The most revealing moment will come after the demonstration ends: the part sticks, the scene has changed, and the robot has to decide what happens next.