OpenAI has turned the AI agent into something closer to a colleague with a desk. Its new Dots have their own cloud computers, can connect to apps and can keep working after the user leaves. That description comes from OpenAI’s product documentation, not an independent test. The consequential part is less the “always-on” label than the permission system around it: a persistent agent must know what it may read, what it may change and when it has to stop for a human.
The shift sounds small only if you imagine today’s chatbots as already autonomous. Most AI conversations are bounded. You ask, the model responds, and the session ends. Even an agent that clicks through a website usually works inside a visible task. A dot can instead hold an ongoing assignment—monitor a project, assemble research or maintain a workflow—and return with progress later. OpenAI says the first dot is included for eligible Pro and Business Premium users, with Enterprise access and additional tiers following its rollout.
That changes the failure mode. A wrong answer in a chat can mislead one decision. A wrong assumption inside an ongoing workflow can be repeated across files, sources and days.
In plain English: A dot is not a smarter reminder. It is an AI process with a persistent workspace and permission to keep doing a defined job between conversations. The cloud computer gives it continuity. The rules and approval gates are supposed to prevent that continuity from turning one mistaken instruction into a chain of unwanted actions.
A Workspace, Not Just a Longer Prompt
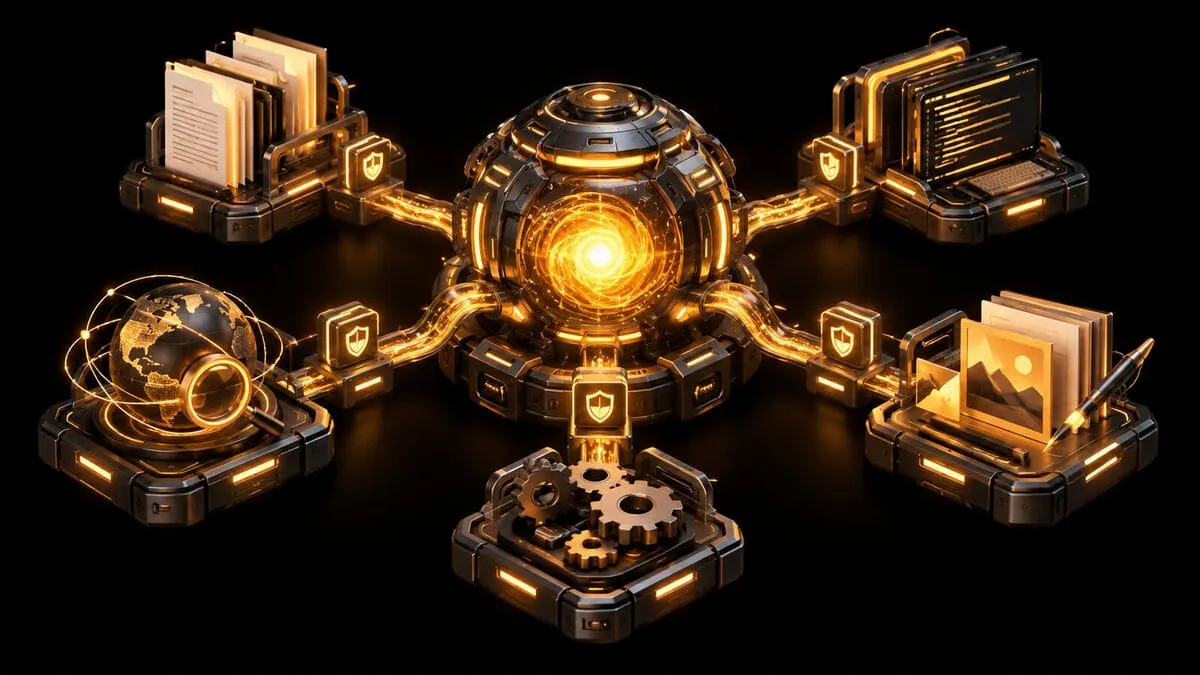
OpenAI’s release notes describe Dots as always-on agents powered by GPT-6 Astra. Each gets a cloud computer and can bring results back for review. That architecture matters because the agent no longer has to reconstruct the whole task from a fresh chat every time.
Think of the difference between leaving instructions on a shared desk and explaining the job again on every visit. The desk can hold documents, intermediate results and a record of what happened. But the analogy has a limit: the “worker” is still a statistical model. It can misunderstand a source, follow an irrelevant clue or confidently generalize from an exception.
OpenAI therefore separates several controls. Users can give a dot custom rules, decide which connected apps it can reach and inspect an Activity View. For proactive research, the company says the agent’s code is restricted to read-only behavior: it cannot send messages, change data or control a browser. When a task calls for action, separate rules and approval requirements apply.
The most interesting layer is auto-review. OpenAI’s GPT-6 Astra system card describes a second model checking proposed actions against policy before they happen. In effect, one AI proposes and another evaluates. Sensitive actions can require explicit confirmation or a handoff to the user.
That is a useful design pattern, but it is not the same as independent oversight. Both systems can share blind spots, and the reviewer sees a representation of the action rather than every consequence in the world. OpenAI reports evaluations built partly from de-identified employee dot activity and deliberately edited disallowed actions. Those tests can show whether the review layer catches known classes of violations. They cannot establish that every novel workflow will be safe.
Permission Design Becomes Product Design
The familiar question for an AI assistant is “How good is the answer?” For a persistent agent, three earlier questions become equally important:
- What information can it see?
- What state can it change?
- Which actions become irreversible without another person?
That is why the permissions are not a compliance appendix. They determine what the product can responsibly do. A research dot with read access to approved folders is one risk. A dot that can send emails, approve purchases and change production systems is another, even if both use the same model.
OpenAI says Dots can make mistakes. We found no independent evidence yet showing how reliably they sustain useful work over days, how often humans must intervene or whether auto-review catches rare but consequential errors outside the company’s test set. This article is an analysis of the published architecture, not a hands-on review.
The next useful evidence will not be another demo of an agent finishing a neat task. It will be operational numbers: completion rates for long-running work, intervention frequency, false approvals, false blocks and recovery after a mistaken action. Until those arrive, the most defensible way to use an always-on agent is to grant the narrowest permissions that still let it be useful.
That lesson connects to the broader memory cliff facing AI agents: persistence is valuable only when the system can preserve the right context. It also echoes the gap between controlled tests and robots working in the real world, where small errors compound outside a benchmark. And it makes access controls like those around Claude for scientific work part of the core capability, not a brake added afterward.
For Dots, the next thing to watch is therefore not how many hours they can run. It is whether OpenAI publishes enough failure and intervention data to show that their permission model works when the agent’s assignment stops being tidy.
Production note: Vastkind reviewed OpenAI’s product documentation, release notes and GPT-6 Astra safety materials. We did not independently test Dots and found no independent longitudinal performance study at publication time.


